A solution for local LLMs nightmare
Like a lot of people nowadays - it's a super trendy subject to be honest - I use open source AI models on local machines.
And as a lot of people, I despair when I look at the price of fancy GPU cards, dedicated mini PC or Apple Mac Studio.
My problem is not really the speed of the LLM request processed, but the abundance of requests : my clients can process dozens or hundreds of requests, in batches. They press a button, they go to take a coffee, we resolve the problem for them. The real problem happens when several clients do the same at the same time : when you are last in the queue, waiting time becomes a real issue.
To address more requests, the usual solution is to get a bigger machine. But bigger machines are expensive. Very expensive.
So really, the only feasible way would be to add more machines - create a kind of LLM farm, or a poor man datacenter. But : my apps point to one specific machine, if I want to use a LLM farm in ly apps, I would need a kind of... LLM router ?
So, helped by my fellow Claude 🤖, I created an app to do exactly that : serving as a router / load balancer / Kubernetes for LLM machines.
It's here and it's free :
https://github.com/AutreMachine/llm-router
The idea is simple :
- You install the Docker on a machine - there is the balancer app and a UI
- You modify in the config.yaml file the ports and the names of the client apps (go to README for more details) - you can then track requests for individual apps
- You launch the UI and you add your local machines
- The system detects the available models ; you add the ones you want in the pool
- You modify your apps to point to the machine serving llm-router
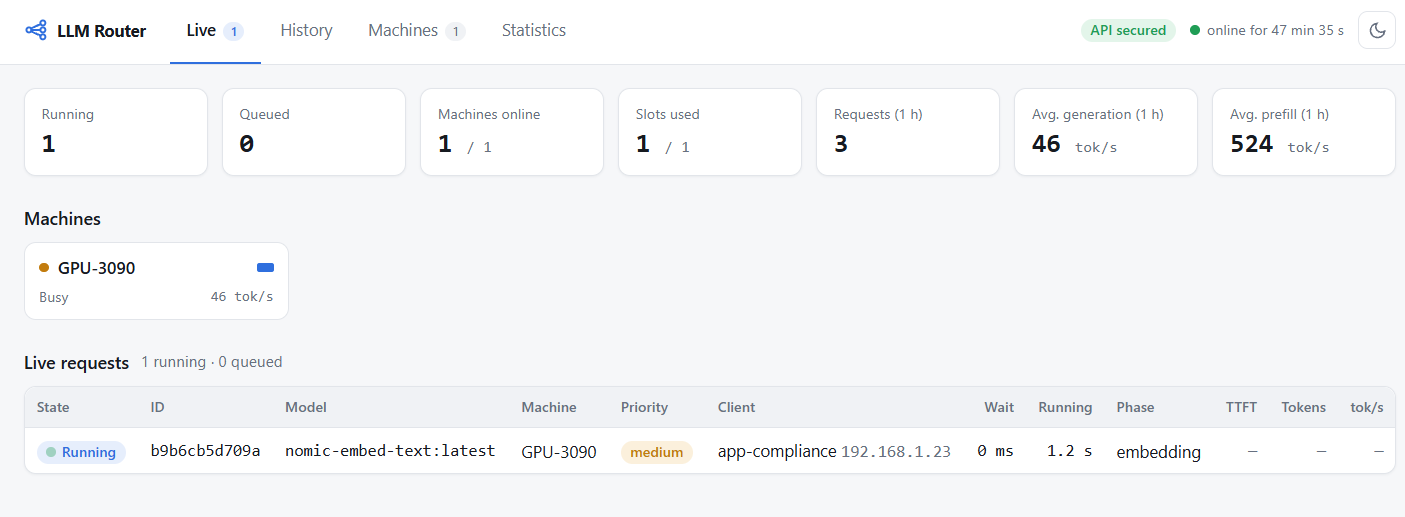
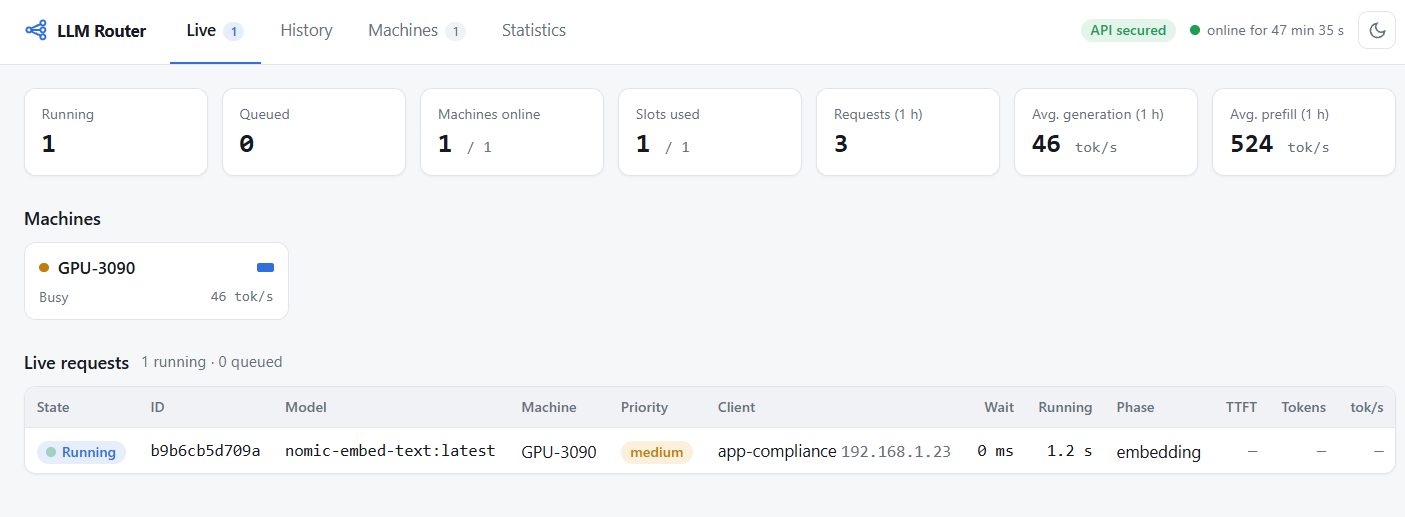
The UI also shows current requests and a history of past requests - helping to check prefill and generation speeds on your machines.
Use cases are multiple :
- You want to reduce the time to serve clients when dealing with a lot of requests by distributing to many machines
- You want to add / remove machines to the pool easily - this gaming machine could sometimes be part of the pool ?
- You want to test a specific LLM version without having to modify your apps configuration
- ...
The sky the limit.
I currently use it to serve my clients, it works well and allows to add different kinds of machines to the pool.
Don't hesitate to comment or ask for new features !